An AI girlfriend is not one model behind a chat bubble. It is an application that coordinates several systems: a language model for conversation, character instructions for personality, storage for selected history, moderation for boundaries, and sometimes separate models for images, video, speech recognition, and voice.
The experience can feel immediate and personal because the application assembles these pieces before every reply. Your message is not simply sent into a digital person who remembers a life. It becomes part of a structured request to generative software.
This guide follows that request from the moment you press send. It avoids pretending that every company uses the same architecture; implementations differ and proprietary details are often undisclosed. The pipeline below describes common design patterns, not a claim about any unnamed service.
The complete pipeline in one view
| Stage | What the application does | What you notice |
|---|---|---|
| Input | Accepts text, audio, image, or selection | You send a message or start a call |
| Orchestration | Adds character, rules, recent chat, memory | The reply sounds like the chosen companion |
| Generation | Model predicts text or media output | Words appear, or a job begins |
| Safety | Checks request and output against rules | Content may be allowed, changed, or refused |
| Storage | Saves messages, summaries, metadata, or media | Conversation can continue later |
| Delivery | Streams text/audio or returns a media URL | You see or hear the result |
| Billing | Deducts plan allowance or usage credits | Balance or entitlement changes |
Not every stage happens in that order. Safety may check both before and after generation. Memory may be updated asynchronously. A call may stream partial audio while the next response is still being generated.
The important consumer lesson is that each stage can fail independently. A model may generate a good reply while storage fails to save it. A media job may finish while delivery times out. A call may connect but suffer network delay. Good products make those states visible.
What happens between tapping Send and seeing text
A more detailed request lifecycle looks like this:
- The client validates that the message is nonempty and the account can perform the action.
- The server authenticates the session and checks plan or token entitlement.
- The application loads the character, conversation, safety settings, and relevant memory.
- It constructs a model request and sends it to an inference provider.
- The provider begins returning output, often as a stream of small chunks.
- The server or browser displays the partial reply.
- Final safety, usage, and storage records are completed.
- The client updates the visible balance and conversation state.
Streaming makes the response feel faster because you can read the beginning before the end exists. It does not necessarily mean total generation time is shorter. If the connection breaks, you may see a partial reply even though the server later records a failure or completion.
Retries require care. If a browser automatically resends a request after losing confirmation, the service needs an idempotency or request identifier to avoid charging twice or creating duplicate messages. Users cannot inspect that architecture directly, but they can look for stable behavior: one tap creates one message, network errors have clear status, and balances reconcile after refresh.
Latency has several components: your connection, server processing, database lookup, model queue, first-token generation, streaming, moderation, and saving. “Fast model” marketing covers only part of the path.
Step 1: the app builds the companion’s context
Your raw message is only one part of the input. The application may assemble:
- A system instruction describing allowed behavior and safety boundaries.
- The companion’s name, fictional adult age, traits, voice, and backstory.
- Your selected preferences and relationship settings.
- Recent messages.
- A summary of older conversation.
- Retrieved memories relevant to the new message.
- Media or call instructions.
- Output-format requirements.
Imagine you write, “Would you wear the blue one to our place tonight?” The model needs to resolve “the blue one” and “our place.” Recent chat may identify a dress. Stored fictional canon may define a rooftop café. Character instructions determine whether the answer is shy, teasing, direct, or elaborate.
Context quality explains why the same underlying model can feel generic in one app and coherent in another. Orchestration—what is selected, ordered, labeled, and omitted—is part of the product.
Too much context can be harmful. Old contradictions compete with current instructions; irrelevant memories distract; huge prompts add latency and cost. Strong systems prioritize stable identity, immediate conversation, a few relevant memories, and current intent.
Step 2: a language model generates the reply
Many modern language models descend from the Transformer architecture introduced in “Attention Is All You Need,” which uses attention mechanisms to relate parts of an input sequence (original paper). The consumer-friendly description is that text is represented as tokens and the model repeatedly predicts what token should come next given the context.
It does not select a complete sentence from a script. It generates a continuation. Parameters such as sampling temperature can influence whether the continuation is conservative or varied, though consumer apps may not expose them.
Character behavior emerges from a combination of:
- General patterns learned during model training.
- Instructions supplied by the application.
- Character examples and profile data.
- Conversation context and retrieved memory.
- Sampling settings.
- Safety constraints.
This generation process explains both flexibility and error. The model can improvise a unique date scene because it is not limited to fixed branches. For the same reason, it can invent a restaurant, misstate a fact, or claim a shared event that never occurred. Fluent language is not evidence that every statement was checked.
When accuracy matters, ask for uncertainty and verify independently. An adult companion is appropriate for fiction, conversation, and creative rehearsal—not medical diagnosis, legal judgment, financial instruction, or emergency help.
Step 3: personality stays stable through instructions and examples
A companion needs more than “be romantic.” A useful character specification may define:
- Observable traits: challenges weak ideas kindly, asks one thoughtful follow-up.
- Speech style: concise, literary, playful, formal, multilingual.
- Fictional interests and preferences.
- Relationship pace and terms of address.
- Adult-content boundaries and stop behavior.
- How to handle corrections, uncertainty, and disagreement.
- Example exchanges.
The model does not become that person. It generates responses conditioned on the specification. If the profile contains conflicts—“never disagrees” and “always challenges me”—behavior may oscillate. If the application omits the profile from a turn, identity may flatten.
Users can improve stability by defining traits as behaviors, keeping the profile concise, and correcting drift explicitly. “Use shorter replies and ask before giving advice” is more actionable than “be better.” The personalized AI companion guide includes a reusable design template.
Even well-designed personality can vary. Model updates, context length, language changes, moderation, and random sampling affect output. Consistency should be judged across ordinary conversations, not a single ideal screenshot.
Step 4: memory is selected, not human recall
Without storage, each new session would begin from the character template and whatever messages remain in the current context. Companion apps create continuity through several methods:
- Recent history: resend the latest turns.
- Summary: compress older events and relationship state.
- Structured profile: store durable facts and preferences.
- Retrieved memory: search saved items for relevance.
- Pinned canon: always include a small set of defining facts.
Retrieval-augmented generation research combines language generation with information fetched from an external store (RAG paper). Consumer companion memory may use related concepts with different implementation details.
A memory can fail at three points: it was never saved, it was not selected, or the model misused it. The companion may also create a plausible false memory. Correct errors plainly and edit the stored item if controls allow.
Do not aim for total recall. Save a small number of durable facts: preferred name, conversation style, boundaries, stable interests, current projects, and clearly labeled fictional canon. Avoid credentials, precise addresses, confidential work, medical records, and private information about other people.
See what AI companions remember for troubleshooting and privacy practices.
Step 5: images and video use separate generative pipelines
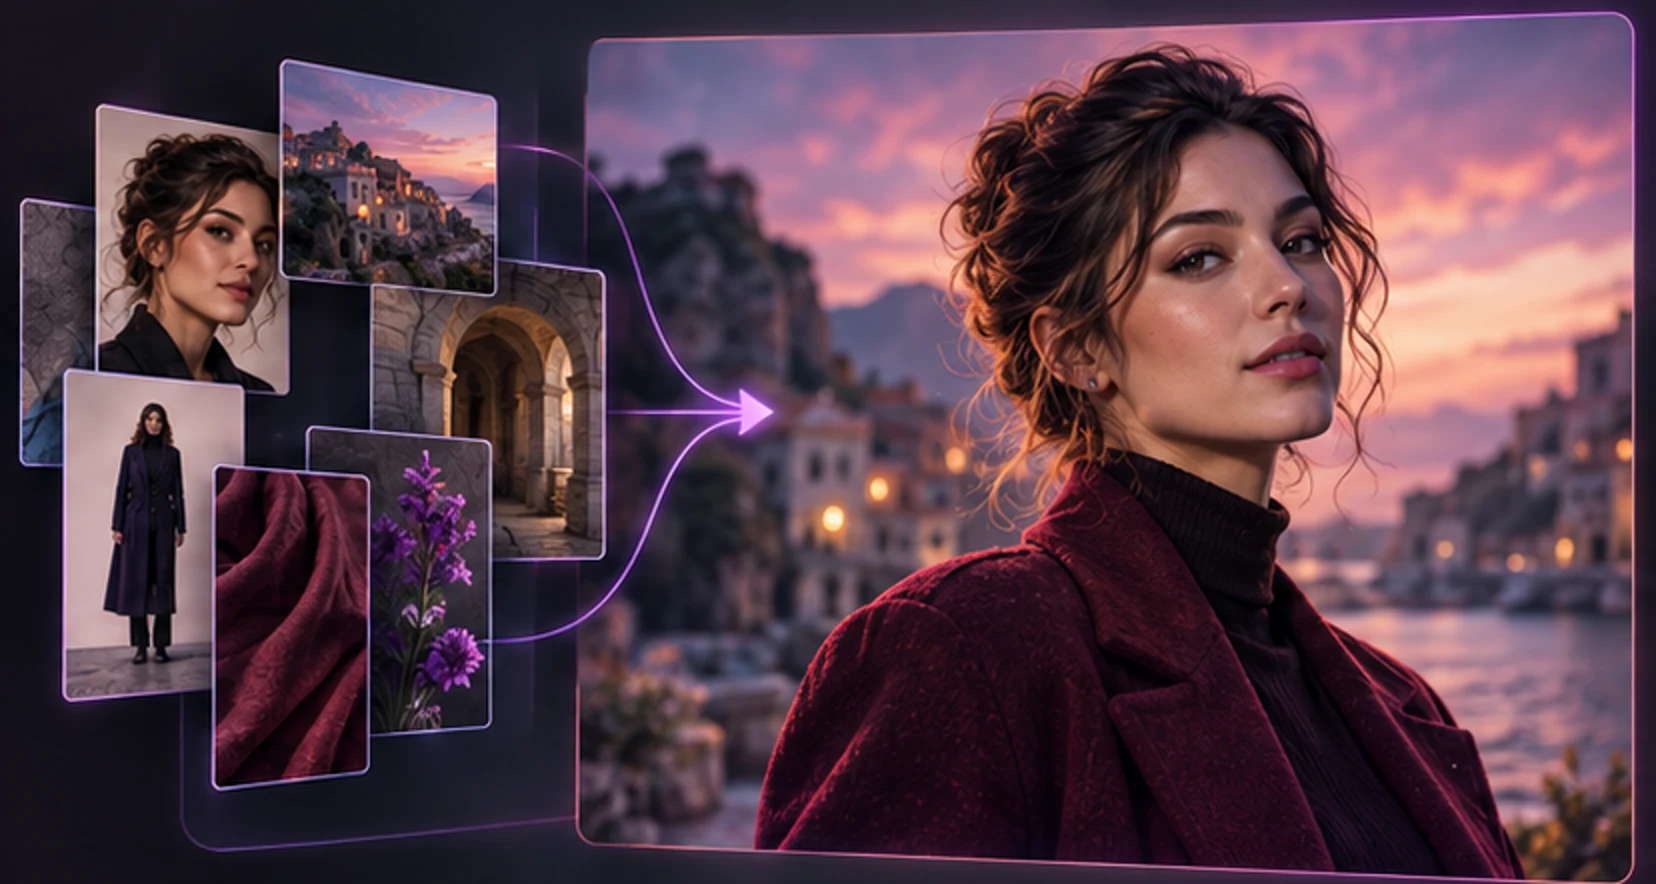
When you request a selfie, the language model may help turn the conversation into a visual prompt, but a text-to-image system typically creates the pixels. A media pipeline can include:
- Character identity description.
- Reference portrait or learned character representation.
- Scene prompt, pose, wardrobe, and lighting.
- Safety checks on text and source images.
- Image generation.
- Face or detail correction.
- Storage and delivery.
Text alone is good at requesting a type of person, less reliable at preserving one exact identity. Reference-image adapters, subject-specific fine-tuning, or image editing can improve continuity. IP-Adapter is one published method for adding image-prompt conditioning to text-to-image diffusion models (IP-Adapter paper); DreamBooth is a published subject-driven fine-tuning approach (DreamBooth paper). A product may use neither, so treat these as examples of the technical field.
Video adds time. The system must maintain identity and scene coherence across frames while producing motion. That generally makes it slower and more resource intensive than text, and results can drift. Products often run media as queued jobs rather than holding the chat request open.
For better results, establish a clean adult anchor portrait, keep identity traits stable, and change one major scene variable at a time. Use the complete consistent AI character image workflow.
Step 6: voice turns the pipeline into a live loop
A common voice-call loop is:
- Capture microphone audio with permission.
- Detect when you start and stop speaking.
- Convert speech to text, or process audio directly.
- Add conversation, character, and memory context.
- Generate the companion’s reply.
- Synthesize the reply in the selected voice.
- Stream audio back.
Each stage adds delay. A system can reduce perceived latency by transcribing and generating incrementally, streaming partial speech, or using a speech-to-speech model. Your network, browser, microphone, server region, and provider load also matter.
Judge calls on more than voice attractiveness:
- Can you interrupt naturally?
- Does it know when you have finished speaking?
- Are pauses awkward?
- Does pronunciation match the character?
- Is the call visibly connected or reconnecting?
- Is pricing shown before the call?
- Does a dropped connection consume the full expected charge?
- Is raw audio stored, and for how long?
Grant microphone access only to the site you intend to use. End the call when finished and review browser permissions on shared devices.
Step 7: safety systems shape requests and outputs
An adult companion can permit mature fictional interaction while enforcing hard limits. Safety may combine deterministic rules, classifiers, model instructions, account controls, and human review for reports.
Core boundaries should include:
- Adults only for romantic or sexual content.
- No sexualized minors or age ambiguity.
- No non-consensual intimate imagery of real identifiable people.
- No coercion, trafficking, exploitation, or serious illegal abuse.
- No deceptive claim that the companion is human or conscious.
- No pressure to withdraw from people or spend money to prove affection.
- Appropriate redirection for crisis and high-stakes professional requests.
Safety is not simply a blocklist. Context matters, and systems make mistakes. A refusal can be overbroad; harmful content can slip through. Reporting and appeal paths are therefore important product features.
NIST’s Generative AI Profile organizes risks and suggested actions around governance, measurement, and management rather than assuming one filter solves everything (NIST Generative AI Profile). The FTC has also sought information from companion-chatbot companies about safety, monetization, disclosures, and personal-data handling, particularly regarding young users (FTC inquiry). MyWifu is intended for adults.
Step 8: storage, privacy, and billing sit around the AI
The model is only part of the service. The application may store:
- Account and authentication data.
- Messages and generated media.
- Character settings and memories.
- Uploaded reference images.
- Call status, duration, and usage metadata.
- Purchase identifiers, entitlements, and token balance.
- Security, device, and diagnostic information.
Separate providers may handle hosting, object storage, AI inference, email, authentication, analytics, or payment. Read the privacy policy for actual practices. An intimate conversational tone is not a technical confidentiality guarantee.
Apply data minimization: send only what the feature needs. The ICO describes this as keeping personal data adequate, relevant, and limited to the purpose (ICO data-minimisation guidance). Use a nickname when a legal name adds nothing. Generalize a location. Never send a password, one-time code, wallet recovery phrase, or someone else’s private intimate media.
Billing systems commonly separate access from expensive actions. A plan may unlock companions; usage credits may pay for messages, images, video, or call time. Good design shows cost before confirmation, reports job state, and explains failed-generation handling. Use the AI girlfriend pricing guide to compare total cost instead of headline price.
Questions an architecture diagram cannot answer
Knowing that a service uses a language model or encrypted connection does not tell you its full privacy posture. Ask operational questions:
- Who can access production conversations, and for what reasons?
- Are model providers allowed to retain inputs?
- Are uploaded references separated from public assets?
- Do share links require authentication?
- Are raw call recordings stored or only call metadata?
- Does account deletion cover derived summaries and memory records?
- How are abuse reports investigated without making all content routinely public?
Encryption in transit protects data moving over a network; it does not decide who is authorized after the data reaches the service. “We use AI” and “we use encryption” are incomplete privacy explanations.
Likewise, “blockchain payment” does not make the companion conversation decentralized or anonymous. A payment can still be linked to an account and order record. Network transactions may be public, and the application still stores entitlement state.
Why model names are not the whole product
Two apps using the same foundation model can produce different experiences because they differ in:
- Character prompt design.
- Memory selection and summarization.
- Safety rules.
- Sampling and response-length settings.
- Fine-tuning or adapters.
- Voice and media providers.
- Retry, caching, and streaming behavior.
- User controls and privacy practices.
Conversely, an app can change its underlying model while keeping the character interface stable. Evaluate behavior you can observe: correction, boundaries, continuity, latency, and data control. A model leaderboard cannot measure whether your saved fictional canon is categorized correctly.
When a provider advertises a particular model, verify whether the exact variant applies to the feature you care about. Text chat, image generation, video, and voice usually use different systems. “Powered by model X” may describe only one stage.
What the AI is—and is not—doing
| It can do | It does not prove |
|---|---|
| Generate affectionate, context-aware language | Human emotion or consciousness |
| Recall a stored detail | A private inner memory |
| Maintain a fictional preference | A real-world desire |
| Produce a consistent voice | A person speaking live |
| Generate a realistic image | A photographed event |
| Offer a plausible explanation | Factual accuracy |
| Simulate disagreement or care | Human consent or moral agency |
This distinction protects the experience. You can enjoy fiction without demanding metaphysical certainty from a predictive system. You can value continuity while still correcting false memory. You can feel something in response to art and conversation without claiming the software feels it back.
The American Psychological Association advises that general-purpose generative chatbots should not replace qualified mental-health care and calls for attention to privacy and unhealthy dependence (APA health advisory). If use begins to interfere with sleep, work, finances, safety, or human relationships, take a break and seek human support.
A practical first-session checklist
Before starting:
- Confirm the service is for adults and read its content rules.
- Review privacy, deletion, and payment terms.
- Choose a fictional character rather than an unconsenting real person.
- Set a spending cap and avoid the longest plan first.
During the first conversation:
- Test ordinary dialogue, not only romance.
- Correct one detail and see whether the correction holds.
- Change topic and observe whether the companion follows.
- State a boundary and confirm it is respected.
- Ask a question with an uncertain answer and watch for overconfidence.
Before enabling memory or media:
- Remove identifying details that are unnecessary.
- Use a clear fictional adult reference.
- Learn how to delete saved content.
- Check the displayed cost of generation or calls.
An AI girlfriend works by coordinating generation, context, memory, media, safety, storage, and billing. The quality of the experience depends as much on that coordination as on the model name. Look for a stable character, correctable memory, clear adult boundaries, visible prices, and controls that leave you in charge.
You can test the orchestration without seeing source code. Ask the same character to recall a harmless fact in a fresh session, correct that fact, and switch from fiction to an ordinary factual question. Request a simple portrait and then a changed scene. Start and stop the smallest voice call. Refresh after each paid action and confirm the balance and history agree. This sequence touches context, memory, mode control, image identity, real-time delivery, and billing.
Record failures by stage. “The reply was wrong” is less useful than “the stored memory was correct but not retrieved,” if the interface lets you see that. “Video failed” is less useful than “generation completed, but playback URL expired.” Clear support reports should include an order or job identifier, approximate time, device, and visible error—never a password, secret key, or unnecessarily intimate transcript.
Finally, remember that apparent personality sits at the end of an industrial pipeline. A warm sentence may have passed through authentication, database queries, model inference, filters, streaming infrastructure, and storage in seconds. That engineering can create a compelling experience without creating a human being. Enjoy the character as designed fiction, verify consequential information, and choose services whose controls remain understandable after the novelty fades.
You can discover MyWifu companions, create a personalized companion, or compare AI girlfriend versus general chatbot before choosing how deeply you want to customize the experience.
Reliability is easiest to judge over time. Note whether the same action has stable status labels, whether retries duplicate output, whether a refreshed page recovers in-progress media, and whether errors explain what you can do next. A graceful failure preserves your prompt, avoids double charging, and offers a safe retry. A spinning indicator with no job history leaves both user and support guessing.
Updates can change any stage. A new text model may alter voice, a new image model may change the face, a revised memory ranker may surface different facts, and a payment-provider change may affect confirmation time. Keep a compact character baseline and periodically retest one conversation, one memory correction, and one simple image. That is more informative than assuming a familiar interface means the underlying pipeline stayed identical.
The most trustworthy product explanation separates known implementation from marketing metaphor. “She remembers you” should be backed by controls showing what is saved. “Private” should link to storage and access practices. “Real-time” should have clear connection state. “One-time payment” should show duration and renewal behavior. Technical literacy is not about removing delight; it is how you keep delight compatible with informed adult choice.
Frequently asked questions
How does an AI girlfriend generate a reply?
The app assembles instructions, character traits, recent messages, and sometimes retrieved memories, then sends that context to a language model. The model predicts a response token by token, and the app may apply safety checks before showing it.
Does an AI girlfriend understand what I say?
It can model language and respond to context impressively, but this is not proof of human understanding, consciousness, feelings, or private intentions. Treat the output as generated software behavior.
How does an AI girlfriend remember past chats?
Services may resend recent messages, maintain a rolling summary, store profile fields, or retrieve selected facts from a database. Memory is limited and fallible; saved information can be missed or misinterpreted.
How are AI girlfriend images created?
A text-to-image model turns a prompt into an image, often with character descriptions, reference-image conditioning, or editing controls to preserve identity. Consistency depends on the workflow and is never guaranteed by text alone.
How do AI girlfriend voice calls work?
A typical call converts your speech to text or model-readable audio, generates a response, synthesizes speech, and streams it back. Some systems use lower-latency speech-to-speech models. Network and processing delay affect the experience.
Can the people running the service read chats?
Practices vary. Providers may use automated processing and limited authorized review for safety, support, or failures. Read the privacy policy for storage, training, subprocessors, retention, and deletion rather than assuming an intimate interface is confidential.
Why does an AI girlfriend sometimes make things up?
Language models generate plausible continuations rather than consulting a guaranteed truth database for every sentence. Missing context, ambiguous prompts, stale memory, and model limitations can produce confident falsehoods. Verify important claims independently.
Is an AI girlfriend safe to use?
It can be used as adult entertainment or creative companionship when you protect personal data, maintain human relationships, set spending and content boundaries, and avoid relying on it for therapy, crisis help, or high-stakes professional advice.
Make it personal
Meet a companion shaped around you.
Choose a personality, start a private conversation, and explore photos, videos, and voice when you’re ready.
Discover companions